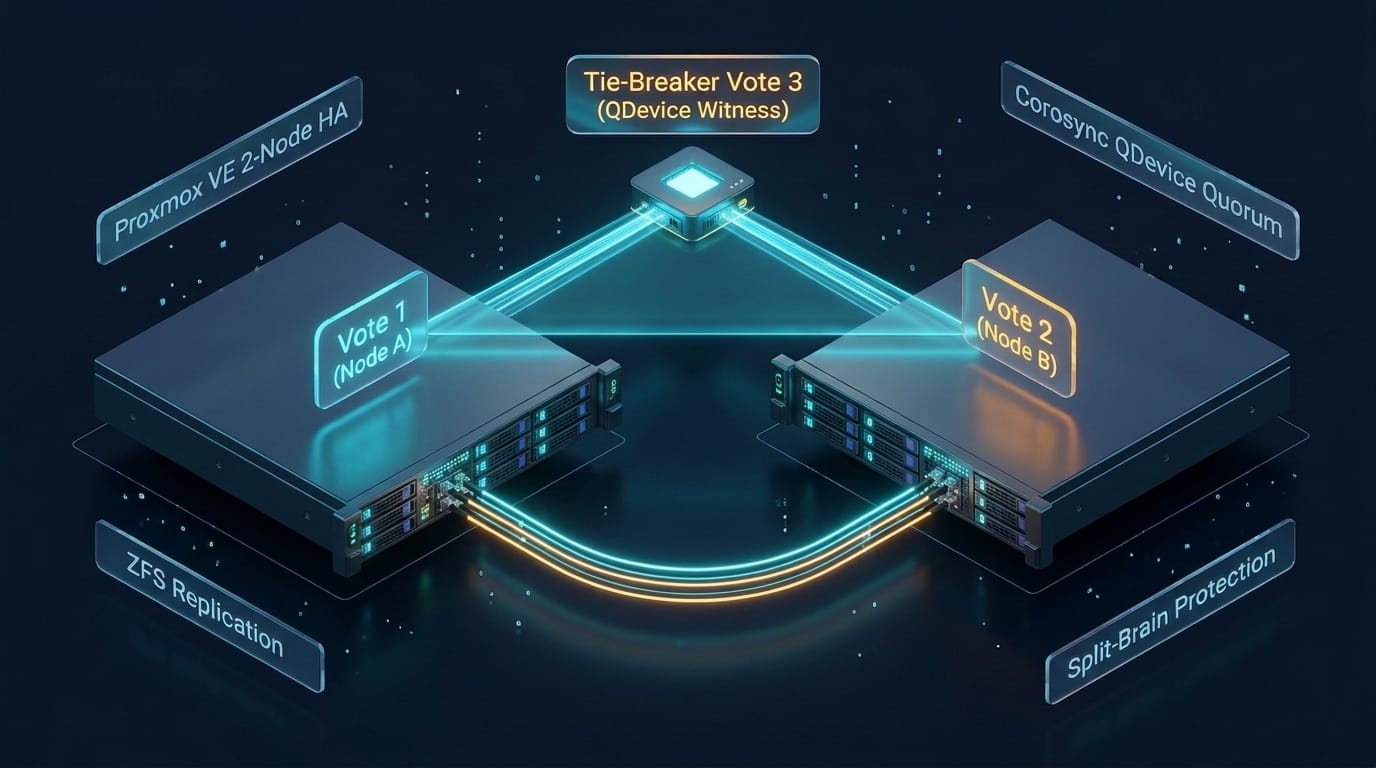
Building a resilient virtualization cluster capable of surviving unexpected physical hardware outages is a fundamental objective for modern infrastructure engineers. However, classical High Availability (HA) clustering rules dictate that split-brain protection requires a minimum of three physical hypervisor nodes to maintain mathematical voting quorum. For growing startups and regional enterprises, procuring three high-specification bare-metal servers represents a substantial budgetary hurdle.
Fortunately, implementing a reliable proxmox high availability 2 node architecture is entirely achievable through the intelligent deployment of an external Corosync Quorum Device (QDevice). By introducing an ultra-lightweight external arbitration witness that holds an active voting tie-breaker, systems administrators maintain strict cluster quorum without the capital expenditure of purchasing a third full-scale hypervisor server. Mastering the nuances of proxmox qdevice corosync quorum unlocks automated virtual machine failover, uninterrupted service uptime, and cost-efficient infrastructure redundancy.
Understanding the Split-Brain Dilemma and Corosync Mechanics
Cluster consensus within Proxmox VE relies on the Corosync cluster engine. Corosync uses a strict majority voting algorithm where the cluster remains operational only when more than fifty percent of assigned votes are actively communicating. In a standard two-node cluster, each node contributes one vote, creating a total of two votes. If network connectivity between the two servers drops, each isolated node sees only its own single vote, which equals fifty percent rather than a strict majority.
Without quorum, the cluster freezes virtual machine operations to prevent split-brain syndrome, a catastrophic scenario where both nodes attempt to write simultaneously to shared storage pools, causing permanent data corruption. By deploying an external QDevice, administrators introduce a third non-computing vote. If one physical hypervisor fails, the surviving node pairs with the QDevice to establish two out of three votes, retaining quorum and automatically launching guest virtual machines on the surviving host. Many technology teams building two-node virtualization fabrics deploy Onlive Server's high-availability dedicated servers to establish resilient physical compute anchors backed by enterprise ECC memory, redundant power units, and multi-gigabit network uplinks.
Deploying and Configuring the External QDevice Witness
The beauty of the Proxmox QDevice mechanism lies in its resource efficiency. The external witness does not require virtualization extensions, high-speed storage, or significant computing capacity. It executes as a lightweight daemon running on any minimal Linux environment, such as a compact virtual instance, off-site monitoring server, or Raspberry Pi single-board computer.
Administrators initialize QDevice integration directly through the Proxmox cluster terminal. After installing the corosync-qnet daemon on the external witness server and the matching corosync-qdevice package across both hypervisors, a single setup command establishes reciprocal cryptographic keys. Corosync automatically updates cluster configuration files across all nodes, integrating the external vote into live quorum calculations within seconds.
Dedicated Corosync Network Links and Latency Thresholds
Because Corosync heartbeats maintain cluster stability, network latency between nodes requires strict operational governance. Corosync transmits high-frequency token packets to verify peer node availability; if packet loss or latency jitter exceeds default timeouts, the cluster can mistakenly assume node failure and initiate unwanted fencing routines.
To guarantee deterministic cluster communication, administrators establish dedicated point-to-point network connections between the two physical servers. Binding Corosync link0 to an isolated physical network card and configuring redundant link1 over the primary network interface creates automated failover protection. Separating cluster heartbeats from heavy VM backup transfers prevents network congestion from destabilizing quorum calculations. In addition, setting static IP assignments and fine-tuning Corosync transport parameters ensures that token transit delays remain well below two milliseconds across production virtualization infrastructure. Maintaining isolated network links shields the cluster against transient broadcast storms, preserving smooth virtual machine orchestration
Shared Storage and Automatic VM Recovery Automation
Achieving seamless automated failover requires pairing Corosync quorum with an appropriate shared storage or real-time replication strategy. In two-node environments where multi-node Ceph storage is impractical due to physical disk constraints, administrators leverage ZFS storage replication over high-speed point-to-point network links.
Proxmox VE includes an integrated ZFS replication engine that synchronizes virtual disk deltas between the two physical nodes at configurable intervals as low as one minute. When the Proxmox HA Manager detects a complete node failure, it verifies quorum via the QDevice and restarts affected guest workloads on the surviving physical host. The virtual machine boots from the most recent synchronized local ZFS snapshot, restoring critical customer services within minutes without manual intervention from sysadmins.
DevOps engineers, systems architects, and infrastructure managers seeking verified configuration syntax, network tuning formulas, and cluster fencing walk-throughs should examine Onlive Server's Proxmox VE high availability cluster guide. Adopting proven high-availability standards allows growing companies to achieve enterprise-grade fault tolerance, predictable operating budgets, and complete operational resilience.